
/display/Documents/JHOVE issues and error messages taken on 2015-10-04.
The original wiki at wiki.opf-labs.org is being decommissioned.
JHOVE issues and error messages
 | This page is under construction. Please feel free to contribute, add, edit and correct  |
Page description: This page is inteded to capture error messages during testing with JHOVE. It also contains some broad PDF knowledge.
- PDF Module
- Dictionary
- Missing dictionary in document node (PdfMalformedException)
- Invalid page dictionary (PdfMalformedException)
- Annotation dictionary missing required type (S) entry (PdfMalformedException)
- Invalid page dictionary object (PdfMalformedException)
- No document catalog dictionary (PdfMalformedException)
- Malformed dictionary (PdfMalformedException)
- Malformed outline dictionary (PdfMalformedException)
- Improperly nested dictionary delimiters (PdfMalformedException)
- Invalid outline dictionary item (thrown at runtime)
- Expected dictionary for font entry in page resource (thrown at runtime)
- Root entry missing in cross-ref stream dictionary (PdfInvalidException)
- Invalid Prev offset in trailer dictionary (PdfInvalidException)
- Invalid Size entry in trailer dictionary (PdfInvalidException)
- Size entry missing in trailer dictionary (PdfInvalidException)
- Trailer dictionary Info key is not an indirect reference (PdfInvalidException)
- Annotation object is not a dictionary (PdfInvalidException)
- Invalid algorithm value in encryption dictionary (PdfInvalidException)
- Outline dictionary missing required entry (PdfInvalidException)
- Invalid dictionary data for page (PdfInvalidException)
- Invalid Names dictionary (invalid and/or malformed)
- Invalid Dests dictionary (invalid and/or malformed)
- Missing expected element in page number dictionary (PdfInvalidException)
- Invalid destination object (PdfInvalidException)
- Invalid Resources Entry in document (PdfInvalidException)
- Improperly formed date (PdfInvalidException)
- Invalid outline dictionary object (thrown at runtime)
- Fonts
- Invalid Font entry in Resources (PdfMalformedException)
- Unexpected error in findFonts (PdfMalformedException)
- Too many fonts to reports; some fonts omitted (Info Messages)
- Cross-Reference Table
- Invalid cross-reference table
- Invalid object number in cross-reference stream (PdfMalformedException)
- Illegal operator in xref table (PdfMalformedException)
- (XMP-)Metadata
- File-Header
- PDF Trailer
- Page Tree & Pages
- Improperly constructed page tree (PdfMalformedException)
- Malformed MediaBox in page tree (PdfInvalidException)
- Document page tree not found (PdfInvalidException)
- Invalid page label sequence (PdfInvalidException)
- Invalid Page tree node (PdfInvalidException)
- Problem with page label structure (PdfMalformedException)
- Bad page labels (PdfMalformedException)
- Invalid page label info (PdfMalformedException)
- PDF Objects
- PdfMalformedException: Invalid name tree Offset: 541014 (thrown at runtime)
- java.lang.ClassCastException: PdfSimpleObject cannot be cast to edu.harvard.hul.ois.jhove.module.pdf.PdfDictionary (thrown at runtime)
- Improperly nested array delimiters (PdfMalformedException)
- Invalid object definition (PdfMalformedException)
- Malformed filter (PdfMalformedException)
- Improper nesting of object streams (PdfMalformedException)
- Annotations
- Invalid Annotation property (+Bsp) (PdfMalformedException)
- Invalid annotation list (PdfMalformedException)
- Invalid characters, syntactic errors
- Issues with Colour-Management
- Interactive Content
- Passwordprotected PDF files
- Miscellaneous
- Workaround OutofMemory (Use Case German National Library)
//TODO: at the moment all the links to the source code lead to the CarlWilson-Version of JHOVE. Eventually, this should be changed to the openpreserve-Version of JHOVE.
//TODO: Maybe there could be some kind of impact gamut?
//TODO: Of course the possible cures have to be tested. Sometimes I just have to guess.
//TODO: The explanations can evolve to be much better, this is only a first try.
PDF Module
Please note that there has not been an update of JHOVE (yet) since PDF 1.6. This is why JHOVE cannot determine the validity for PDF 1.7 (and higher) for sure, although it gives a nice clue about it of course. For the same reason JHOVE cannot really deal with PDF/A-2, as this is built on PDF 1.7.
JHOVE can throw two different kinds of exceptions: a PDFMalformedException and a PdfInvalidException.
Well-Formedness
To be considered as well-formed by JHOVE, a PDF must consist of:
- a PDF Header (starts with %PDF and the version of the PDF)
- a EOF-Tag (End-of-File-Tag)
- a body consisting of well-formed objects
- a cross-reference table
- a trailer defining the cross-reference table size
- an indirect reference to the document catalog dictionary
Validity
A valid PDF must be well-formed. In Addition to that, is has to fulfill the following criteria:
- The file is well-formed.
- The document structure conforms to the specification. This includes (when present) outlines, pages, the page label tree, attributes, resources, role maps, name trees...
- Version information in the document catalog dictionary, if present, is properly formed.
- Dates are properly formed.
- File specifications are properly formed.
- Any annotations are properly formed.
- Any ArtBox, BleedBox, MediaBox and TrimBox items are PDF rectangles.
- XMP data, if present, are well-formed.
Dictionary
dictionary: "collections of objects indexed by Names" (wikipedia)
A PDF file consists of PDF objects, which are referenced by the dictionary. The PDF dictionary is embedded between << these paratheses >>. An example: <</Subtype /Type1C/Length 886/Filter /FlateDecode>>
A PDF dictionary entry constits of a pair of values and always starts with a key which is introduced with a Slash ("/") and is followed by the value. Possible keys which are described in the PDF specification are:
- /LastChar: takes a number as a value
- /BaseFont: takes a string constant value
- /Type
- /Encoding
- /Subtype
- /Filter
- /Font Descriptor: points to another object
In theory, it is possible to add own keys, but these are then ignored by the Acrobat Reader. For long-term-availability, this does not seem to be a good idea anyway.
Missing dictionary in document node (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
line 104 in DocNode class |
This error/exception is thrown if there is no PdfDictionary. The code checks if "_dict == null" and if it is null (=not there), the error is thrown. As a Pdf Dictionary is mandatory for a well formed PDF, this error leads to a malformed PDF. | A missing Pdf Dictionary is a real error /lack, which should not be accepted. | Is it possible to build a Pdf Dictionary as an afterthought? Maybe iText can fix it. We (at ZBW) have an iText-Tool, which just copies each page into a new PDF. The PDF structure gets repaired by this procedure and I would guess that it would build a brand new PDF Dictionary for the PDF. I do not have any example by hand, though, so I cannot check. |
Invalid page dictionary (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Line 2846 of the class PdfModule. |
Annotation dictionary missing required type (S) entry (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Line 3097 of the class PdfModule Thrown like this: throw new PdfMalformedException ("Annotation dictionary " + "missing required type (S) entry"); |
Invalid page dictionary object (PdfMalformedException)
| Source Code | Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Line 1708 of the class PdfModule. |
No document catalog dictionary (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfModule line 1347 String "nocat" |
If the catalogue entry == null, the Error is thrown and SetWellFormed is set on false. |
We are allowed to use and share this PDF , the producer has provided it as an example. |
Malformed dictionary (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| classParser in line 364 |
If the error is thrown in the catch-Block, there are no further information. Otherwise, it is saved as String "invalidDict" and the error can be "invalidDict" + ....some details. An example can be if the vector has a non-even number of objects. An example of an error is: Malformed dictionary: Vector must contain an even number of objects, but has 29 |
An example for an error message here is: Malformed dictionary: Vector must contain an even number of objects, but has 29 |
Malformed outline dictionary (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| classPdfModule in line 3840 but seems to be commented? |
Improperly nested dictionary delimiters (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| line 100 of the classParser. |
If a certain value is less than 0, something about the order is wrong and the error is thrown |
Invalid outline dictionary item (thrown at runtime)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| class PdfModule in line 3858 |
|
Expected dictionary for font entry in page resource (thrown at runtime)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| not found in source code | Cabinet of Horrors Sample has a PDF example that can be openly used |
Root entry missing in cross-ref stream dictionary (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| class PdfModule in line 1050 |
error thrown if root entry == null Example for a root entry: <</Root 335 0 R/Info 333 0 R/ID[]/Size 347/Prev 37150797>> |
Invalid Prev offset in trailer dictionary (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| classe PdfModule in line 1094 |
An if/else checks wether some value is less than 0 |
Invalid Size entry in trailer dictionary (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| class PdfModule in line 1115 |
If a value is either less than 0 or bigger than 8388607, this exception is thrown. Obviously, appendix C is limited if it is a PDF/A and is not allowed to be bigger. |
Size entry missing in trailer dictionary (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| https://github.com/gmcgath/jhove/blob/master/src/main/java/edu/harvard/hul/ois/jhove/module/PdfModule.java PdfModule in line 1129 |
||||
| |
Trailer dictionary Info key is not an indirect reference (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfModule in line 1138 |
Annotation object is not a dictionary (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfModule in line 2752 |
Invalid algorithm value in encryption dictionary (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfModule in line 1574 |
Outline dictionary missing required entry (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfModule in line 3811, but it's commented? |
Invalid dictionary data for page (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| classPageObject in line 74 as String "badPageStr" |
if entries in the dictionary are == null, this error is thrown |
Invalid Names dictionary (invalid and/or malformed)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfModule line 1453 |
Invalid Dests dictionary (invalid and/or malformed)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfModule line 1491 |
Missing expected element in page number dictionary (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| 182 in class PageLabelNode |
if the PdfArray object == null this error is thrown |
Invalid destination object (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| classDestination in line 93 |
There are several valid destination objects: An unnamed, direct destination, which refers to the page object. An unnamed, indirect destination, which refers to a named, direct destination, which refers to the page object. If it is no PDFArray and no PdfDictionary, this error is thrown. Can occur more than once in one PDF file. |
Invalid Resources Entry in document (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Line102 in DocNode saved as string "invres" |
Can be thrown in 2 cases. If the entries are not "null"/are not there, this would lead to another error ("missing dictionary in document node") |
Improperly formed date (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Class PDF line 4099 |
e. g. this date is not syntactically correct: /CreationDate (Freitag, 11. Dezember 1998 14:47) This would be correct: XMP: <xmp:CreateDate>2014-12-09T10:25:10+01:00</xmp:CreateDate> <xmp:ModifyDate>2014-12-09T10:25:10+01:00</xmp:ModifyDate> Keyword-section: <</Keywords()/ModDate(D:20141209102510+01'00')/CreationDate(D:20141209102510+01'00')/Producer(iText® 5.1.0 ©2000-2011 1T3XT BVBA)/Author(Andreas Knorr)/Title(Diskussionspapier Nr. 12)>> |
It may happen that after a "cure" there is no information about the creation date any more, if there are no xmp metadata in the original PDF. The date is written "badly enough" that some tools might not regocnize the entry and do not translate it into the new / corrected PDF. |
use this as a reference, but find a better example (or build one) eventually |
Invalid outline dictionary object (thrown at runtime)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| not found in source code |
Fonts
Non embedded fonts are one of the biggest risks for the correct rendering of PDF files. If one of the used fonts is not embedded ind the PDF and the rendering device does not have the font, the PDF might not be rendered as the data producer once has intended. It even can lead to missing text, gaps within words or text shifting. The worst case would be that part of the text cannot be displayed correctly any more.
Some fonts cannot be embedded due to copyright reasons. Furthermore, there can be name conflicts. Somebody saves his font as "myfont", does not embedd the fonts and the rendering device also has a font named "myfont" and chooses this font to render the text - which is indeed a very different font and changes the visual impression of the PDF a lot.
It is not mandatory for ISO-3200 to mbedd fonts. A non-embedded font does not necesarily lead to an invalid PDF. With PDF/A, however, this is different, every used font has to be embedded.
Therefore, an absolute valid PDF can be at risk for long-term-availability if the fonts are not embedded. Here is an extrem example (from a slide from the PDF Days in Baseln in 2012): 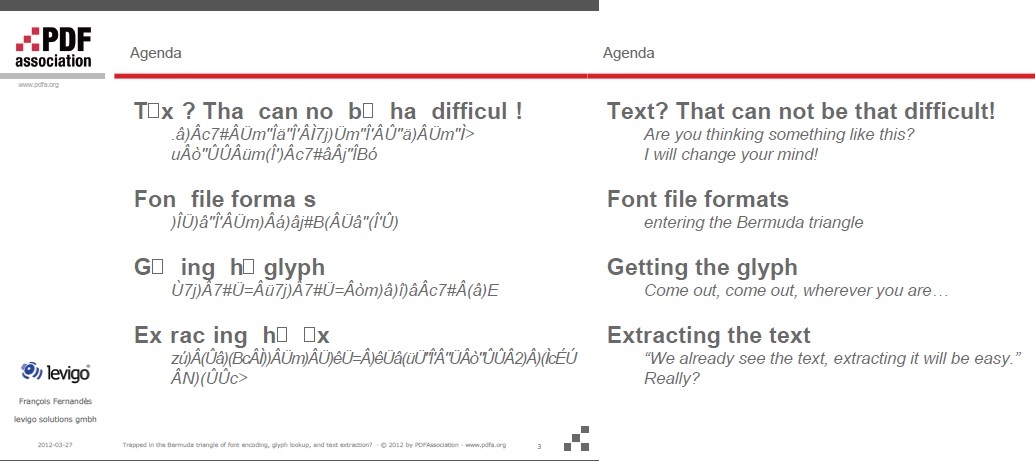
Invalid Font entry in Resources (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| classDocNode, line 138 |
A try-catch block catches entries in the PdfDicitonary if something is amiss. |
Unexpected error in findFonts (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Line 2248 in PdfModule |
Too many fonts to reports; some fonts omitted (Info Messages)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| The boundary should be at 1000 different fonts in one PDF |
Cross-Reference Table
The cross-reference table serves which indexes all the objects in the PDF file. It is shown as an "byte offset" which displays the exact number of bytes from begin of the file where the object starts.This is useful as the software can find an object within the PDF file without having to scan the whole PDF. It is like an exact adress within the PDF file.
In contrast, this is not possible with a TIFF-file, because this is not linearised and that is why a TIFF file cannot be streamed.
An example for a cross-reference table:
xref
334 13
0000000023 00000 n
0000000547 00000 n
0000001140 00000 n
0000001328 00000 n
0000002384 00000 n
Invalid cross-reference table
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfModule Line 1022 |
Invalid object number in cross-reference stream (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| line 1228 class PdfModule |
PDF Files in Cabinet of Horrors |
Illegal operator in xref table (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| line 1323 in class PdfModule |
Legal operators seems to be "n" and "f". |
(XMP-)Metadata
eXtensible Metadata Plattform
XMP is based on XML and XMP Metadata can be found not only in PDF (of course), but as well in TIFF, JPEG and other file formats. The most popular XMP scheme is Dublin Core, but there are others as well. XMP Metadata is possible since PDF 1.4, earlier versions should not contain XMP metadata. There is a SDK (Software Development Kit) to work with XMP directly from Adobe.
PDF/A asks for certain XMP metadata, usually Preflight will fix that easily.
Invalid or ill-formed XMP-metadata (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfModule line 1757 |
File-Header
The Header usually has 1 or 2 lines. The first one is mandatory and can look like this: %PDF-1.7
The first four bytes have to be "%PDF", which is handy to check if it is a PDF file or not, because you only have to read the first four bytes.
The following data in the header usually shows to applications and software like email clients or file-transfer-software that it is binary data and not just plain ASCII-text.
Invalid Version in document catalog (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfModule line 1447 |
If the header and the dictionary do not show the same version, only an InfoMessage is shown. But the catch-block throws an error. |
No PDF Header (thrown at runtime)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Not found in source code | PDF example that is indeed an xml but the user did not realise the PDF was not downloaded |
PDF Trailer
“that specifies the location of some special objects (amongst which the cross-reference table)” „The trailer contains the location (byte position) of the cross-reference table, as well as some other special objects.“
The structure looks like this:
<</Size s /Root r v R ... any other data >>
startxref #
498
%%EOF
s = How many entries (objects) does the xref table contain?
root = Root node of the PDF fiile
r = reference number
v = version of Object
startref # shows where the xref table starts, afterwards the eof-tag follows.
Invalid PDF Trailer (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| |
Very often the upload of a PDF has stopped and the last part is missing. No %EOF can be found |
PDF example |
Invalid ID in trailer
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| line 1146 in PdfModule |
No PDF Trailer
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Cannot be repaired (I guess), because the PDF is not complete |
Page Tree & Pages
Improperly constructed page tree (PdfMalformedException)
TODO: There is more info in the german wiki which has to be translated.
Das stammt aus der Java-KlassePageTreeNode.
Dieses Beispiel-PDF kann als Beispiel genutzt werden, da es eigens zu Testzwecken erstellt wurde. Es gibt 2x den Fehler "improperly constructed page tree" aus und ansonsten keine weiteren Fehlermeldungen und wird von JHOVE als "not well-formed" eingestuft.
Während desPDF Hackathon der OPF (Open Presentation Foundation) gemeinsam mit der ZBW (Deutsche Zentralbibliothek für Wirtschaftswissenschaften) und Goportis (Leibniz-Bibliotheksverbund Forschungsinformation) in Hamburg wies Olaf Drümmer von der PDF Association auf eine interessante false negative Fehlermeldung von JHOVE hin.
Die Seiten einer PDF-Datei sind in der Regel in einem Page Tree gespeichert, um möglichst rasch auf eine bestimmte Seite gelangen zu können[[2]|http://zbwintern/wiki/display/dLZA/Ein+PDF%2C+das+Jhove+als+solches+anerkennt#_ftn2]. Dieser wird häufig als balancierter Page Tree gebildet. Obgleich der PDF-Standard auf diese Möglichkeit hinweist, schreibt er sie in keiner Weise vor.
Die Seiten können auch in einem einfachen Array aus Seiten gespeichert werden, auch das entspricht dem PDF-Standard. Es ist lediglich weniger effizient beim Seitenzugriff (schlechtere Performanz), vor allem wenn es sich um eine PDF-Datei mit besonders vielen Seiten handelt. JHOVE hingegen gibt es als Fehler aus, wenn die Seiten in einem Array anstatt in einem Page Tree gespeichert sind. Da dies kein Fehler ist und für die digitale Langzeitarchivierung nicht risikobehaftet, kann diese Meldung ignoriert werden.
Zitat aus dem PDF-Standard (ISO 32000-1 aka PDF 1.7) unter 7.7.3 Page Tree / 7.7.3.1 General:
"NOTE The simplest structure can consist of a single page tree node that references all of the document’s page objects directly. However, to optimize application performance, a conforming writer can construct trees of a particular form, known as balanced trees. Further information on this form of tree can be found in Data Structures and Algorithms, by Aho, Hopcroft, and Ullman (see the Bibliography)."
Es wird also rein informativ darauf hingwiesen, dass page trees sinnvoll sind. Allerdings muss man sich zu page trees außerhalb des PDF-Standards informieren (Quelle wird genannt). Es ist in keiner Weise vorgeschrieben, dass man page trees nutzen muss. Ein bestimmter Schwellwert wird nicht genannt - Leonard Rosenthol hat m. E. in seiner Monographie (Developing with PDF: Dive Into The Portable Document Format by Leonard Rosenthol, page 24) von 50 gesprochen, Olaf Drümmer hat berichtet, dass ein Adobe-Mitarbeiter ihm von einem Test erzählt hat, bei dem sie auf 64 gekommen sind, das hängt aber stark vom Material ab. Es ist davon auszugehen, dass es ungefähr in der Liga spielt, bei 5 oder 1000 liegen die Werte bestimmt nicht.
Weitere PDF-Dateien mit dieser Fehlermeldung weisen ebenfalls die Besonderheit auf, dass die Fehlermeldung 2x auftaucht. Könnte man ggf. anhand des SourceCodes nachvollziehen.
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
Malformed MediaBox in page tree (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Line 154 in DocNode |
There has to bei a rectangle: PDF Rectangle: Any ArtBox, BleedBox, MediaBox and TrimBox must be compliant PDF rectangles. E.g. /Rect [2 3 4 5] which specifies the X and Y coordinates of the upper right and lower left corners of the rectangle. |
Document page tree not found (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Line 1703 in PdfModule |
error is thrown if the _pagesDictRef == null It is filled with null at the beginning but should be filled with some value afterwards. |
Invalid page label sequence (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| line 2893 PdfModule |
Invalid Page tree node (PdfInvalidException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| class PageTreeNode |
Problem with page label structure (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Line 2941 of the class PdfModule |
Bad page labels (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Line 2655 of the class PdfModule |
Invalid page label info (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Line 2735 of the class PdfModule |
PDF Objects
In general there are 8 object types in a PDF and one special object type (so 9 all in all), that are supported by the PDF format. Six are scalar types (containt only one value/object) and three are container types that can contain more than one value. These are dicitionary, array and stream. There are tools from [Adobe which can be used for the object analysis.
| [https://blog.idrsolutions.com/2009/04/viewing-pdf-objects/]] |
//TODO: translate the rest
- Boolean Objects: true / false
- Numeric Objects: integer or real numbers
- String Objects: Sequenz from 8Bit-Bytes, which represents text: Literal Strings, hexadecimal Strings. PDF 1.7 allows for Text Strings, PDFDocEncoded Strings, ASCII Strings & Byte Strings.
- *Name Object: *Charakerfolge, die mit einem Slash („/“) eingeleitet wird. Leerzeichen und einige bestimmte Delimeter-Charaktere sind in Namen nicht erlaubt, können aber dargestellt werden, indem stattdessen der korrespondierende Hexadezimalcode verwendet wird.
- Array Object: only one-dimensional arrays. All object types in an array are possible, even other arrays. Always displayed with [ ] .
- Dictionary Objects:
- Stream Objects: Eine Sequenz von Bytes, die unbegrenzt lang sein können, ganz im Gegensatz zu String Objects. Ein Stream Object beginnt immer mit einem Dictionary, das die Byte-Sequenz beschreibt (Größe, Filter, Dekodierungsparameter) und dann folgt der Stream, der zwischen „stream“ und „endstream“ eingeschoben ist. Hier ein Beispiel:
2 0 obj
<</Length 39>>
stream
BT
/F1 12 Tf
72 712 Td (A short text stream.) Tj
ET
endstream
endobj
8. Null Object: An einigen Stellen wird empfohlen, ein Objekt besser ganz zu löschen anstatt es auf null zu setzen. Im JHOVE-Code gibt es viele „== null“-Abfragen, die oftmals beim Zutreffen zu einer Exception führen.
9. Indirect Objekt:
PdfMalformedException: Invalid name tree Offset: 541014 (thrown at runtime)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| thrown at runtime, not in source code |
can occur more than once in one PDF |
java.lang.ClassCastException: PdfSimpleObject cannot be cast to edu.harvard.hul.ois.jhove.module.pdf.PdfDictionary (thrown at runtime)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| This does not shown in the GUI, only in the java-library-version I have a long german explanation which I can translate someday. Seems to be a JHOVE Bug and not a real PDF error. |
example from the BSB another example in a forum PDF |
Improperly nested array delimiters (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| class Parser line 109 |
If a certain value is less than 0 this is an indicator for a wrong order. |
Invalid object definition (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| class Parser |
PDF from the Cabinett of Horrors |
Malformed filter (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfStream line 204 |
A filter has to be either an instance of the PdfDictionary or of the PdfArray. Otherwise, it is malformed. (To my humble understanding, needs to be checked.) |
Improper nesting of object streams (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfModule line 2408 |
Annotations
All annotations need to be well-formed.This is quite similar to the definition of a well-formed xml, but as an xml usually is far less complex, it is easier to tell and to parse.
Example:22 0 obj
<< /Type /Annot
/Subtype /Text
/Rect [266 116 430 204]
/Contents (The quick brown fox jumped over the lazy dogs.)
>>
endobj
Invalid Annotation property (+Bsp) (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfModule line 3159 |
PDF (from the Cabinet of Horrors) |
Invalid annotation list (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfModule line 2780 |
Invalid characters, syntactic errors
Invalid character in hex string (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| class literal line 360 & classe tokenizer in line 820 . |
There is an if/else which tests which HexValues are allowed/valid and which are not. Invalid lead to an invalid PDF. |
The NLNZ has an example but it's not possible to share it. |
Issues with Colour-Management
The PDF format works with image data streams and not with image file formats. The most important filter/compressions are:
- 1 Bit Data: Fax-Kompression group 3 or 4, JBIG2
- gry shades, RGB or CMYK Daten: JPEG, JPEG2000 (DCTDecode is the filter JPEG uses)
- usable for all kind of image data: ZIP
- alternatively LZW can be used, this is not posisble in PDF/A-1 as the patentdid not expiere before 2004
- RLE (Run Length Encoding) is possible, but is usually not used because it is not efficient
It is possible to embedd the kind of data stream in a PDF which would also be used by a JPEG or JPEG2000. Only the data stream is used which deals with the image itself, no information like metadata is added to that.
A TIFF image would be stored in a PDF e. g. like a JPEG, a TIFF itself cannot be embedded 1 to 1 in a PDF (which is possible with a JPEG).
Compression method is invalid or unknown to JHOVE (PdfMalformedException)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| PdfModule line 2454 |
ty/catch, if "ZipException". Is zip the only kind of compression JHOVE knows? But there should be 4 other ones for image data streams. |
Interactive Content
Interactive content often depends on extern information, which can lead to problems and limited functionality. Sometimes fill-in-forms are presented differently.
Passwordprotected PDF files
In general, JHOVE can deal with passwordprotected PDF files. This does not lead to invalidity (exception: PDF/A). The boolean value "_encrypted" just is set on true. Some JHOVE versions even return this value in the output (German National Library's version, mine does not). So it should be possible to use JHOVE just to determine Passwordprotection, but of course JHOVE might be too "big" for such a relatively small task.
Miscellaneous
Lexical Error (thrown at runtime)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Not directly found in source code. (check "TokenMgrError") |
java.lang.NullPointerException (thrown at runtime)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| Can occur whenever some needed object is null. |
Too generic to be able to determine the impact for this error in general, depends on the occasion. |
java.lang.OutOfMemoryError (thrown at runtime)
| Source Code |
Explanation |
Impact |
Cure |
PDF Example |
|---|---|---|---|---|
| The PDF might be perfectly valid, there is just too much space needed to validate |
A possible reason might be a very big dictionary because of very many images. 10,000 images are no problem, but an unlimited number of images can lead into problems, if the PDF is built from very many images. (There is a nice use case of the Germany National Library, which we can probably borrow.)
Workaround OutofMemory (Use Case German National Library)
JHOVE can run out of memory space during the PDF examination. Some exapmles are listed in the SourceForge Bug Reporter.
Very big dictionary because of too many listed pictures
The German National Library in Frankfurt has found out that JHOVE causes the java heap space to run full if there are too many listed pictures in the PDF Dictionary. They have developed a workaround for this issue to keep java from failing.
PDFModule.java > findImages// DNB
// heins, 2014-10-30
if (_imagesList.size() <= DEFAULT_MAX_IMAGES) {
_imagesList.add (prop);
}
The DEFAULT_MAX_IMAGES depend. PDF/A allows 4095 entries. Tests have shown that 10,000 would be also ok. But no limit causes a heap space error around 1,251,900 entries. This will surely have more dependencies, so these numbers are from a test the German National Library has conducted.
(//TODO: as the DNB has agreed to share this use case, this will be described in more detail soon)