Archived copy.
This page was recovered from the Internet Archive snapshot of
/pages/viewpage.action?pageId=13764627 taken on 2022-12-02.
The original wiki at wiki.opf-labs.org is being decommissioned.
Analysis of Lucene Index Word Frequency
| One line summary | Create a word frequency list from a Lucene index and try to ascertain the subject matter of the collection that the index was created against. |
| Detailed description | The solution for Characterising Externally Generated Content generated a Lucene index of the collection content. A small piece of Java code was developed to scan through the terms in the text content field of the Lucene documents (the metadata wasn't trawled). A list was created of the terms in the index and the frequency of the terms (the number of times that they occurred in the index). The initial results were disappointing as Lucene indexed all of the words and the most frequently used words were ones that occurred commonly in plain English. The General Service List http://jbauman.com/aboutgsl.html  is a list of commonly occurring words deemed to be most useful to people learning English, and their frequency. Andrew Jackson used this list to determine how much more frequently words were used in the Lucene index, in comparison to "common English", as defined by the GSL. |
| Solution champion | Andrew Jackson |
| Git link | The analysis results (Spreadsheets, csv files, Lucene index, etc.) have been checked into GIT here : https://github.com/openplanets/AQuA/tree/master/word-freq-compare |
| Evaluation | |
| Tool | Excel |
| Issue |
Unknown born-digital file history |
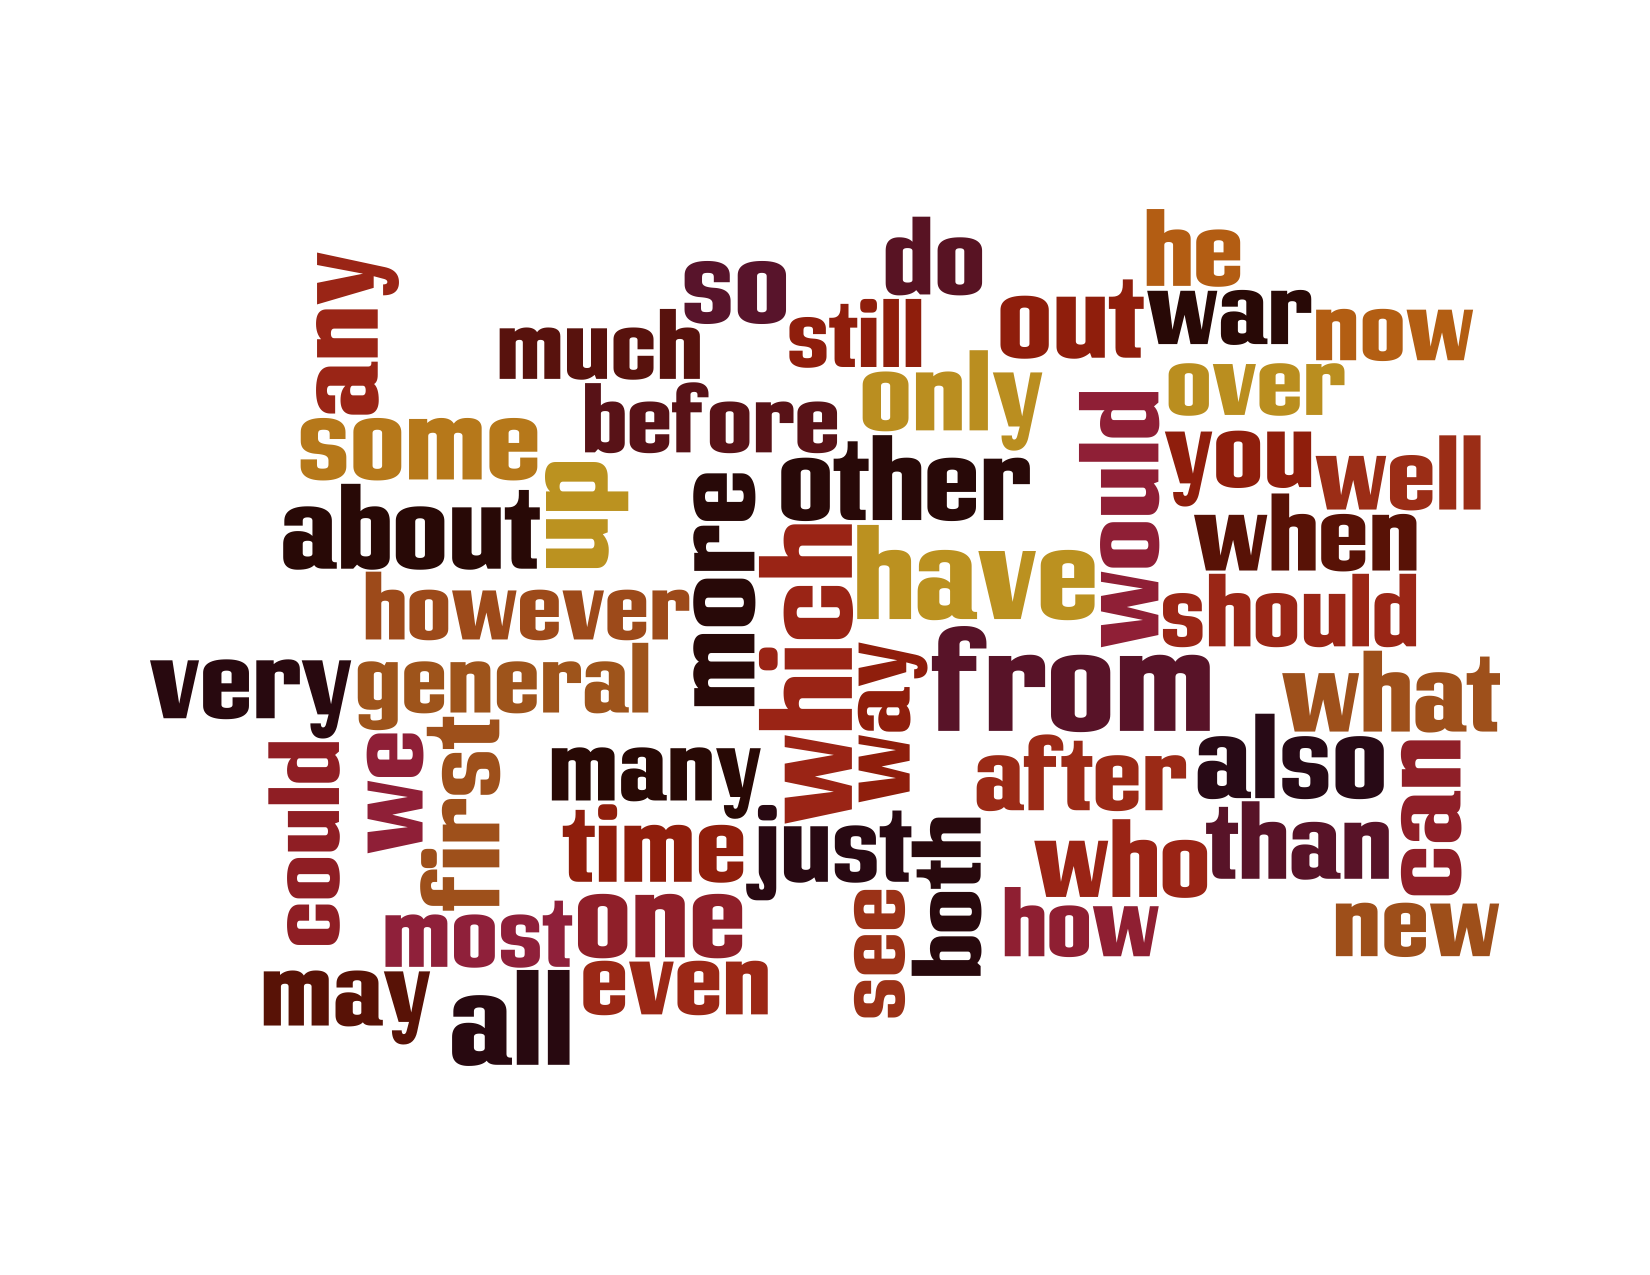
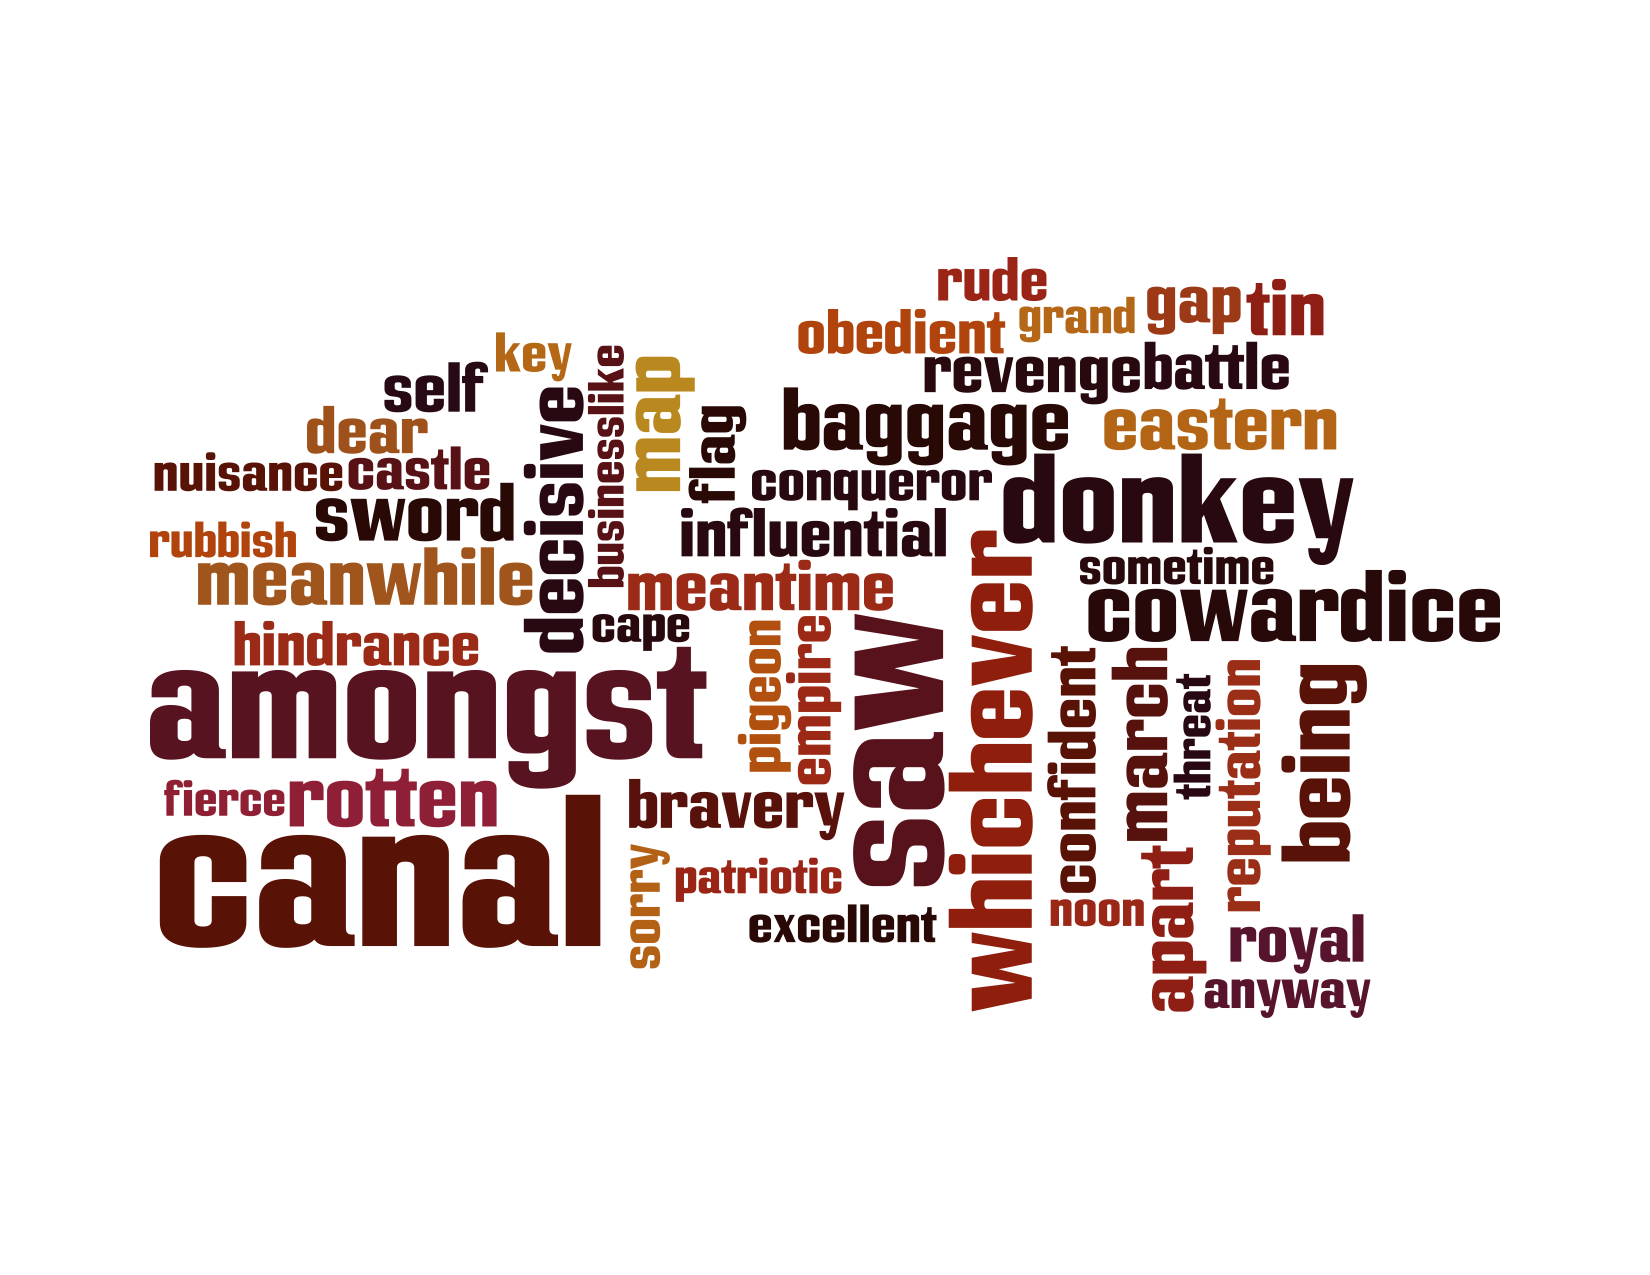
Word frequency clouds
Absolute word frequencies
|
Word frequencies relative to common English usage
|